Lecture 30 Weighted regression
30.1 Introduction
So far we have changed the mean model: which predictors enter and how they enter. Weighted least squares changes the error model. Some responses are measured more precisely than others, so their deviations from the fitted mean need not contribute equally.
If observation \(i\) has error variance \(\sigma_i^2\), the usual precision weight is proportional to \(1/\sigma_i^2\). A more precise observation receives a larger weight. We will start with means based on different numbers of people, then use the same rule when individual error variances change across the predictor range.
30.2 Weighting by Sample Size
The CPS5 data contain individual wages and characteristics for 528 employees. Here we focus on education (ED) and hourly wage (WG). Goldberger first averages wages within each education level, from 6 to 18 years, then regresses those group means on education. Most employees had 12, 14 or 16 years of education.
Each row here is a mean hourly wage for one education level, not one person. Suppose individual wages within the education groups have a common variance \(\sigma^2\) and are independent. A mean based on \(n_j\) people then has variance \(\sigma^2/n_j\), so inverse-variance weighting gives \(w_j \propto n_j\). This explains why the group containing three people should have less influence than a group containing many more.
30.2.1 CPS5 grouped data
   EDgroup  AvWage  SEMean   StDev   N
1        6  4.4567 0.79805 1.38226   3
2        7  5.7700 0.83690 1.87136   5
3        8  5.9787 0.62779 2.43142  15
4        9  7.3317 1.29904 4.50000  12
5       10  7.3182 0.64444 2.65711  17
6       11  6.5844 0.64084 3.32992  27
7       12  7.8182 0.25206 3.72159 218
8       13  7.8351 0.66765 4.06114  37
9       14 11.0223 0.92157 6.89643  56
10      15 10.6738 1.39739 5.03837  13
11      16 10.8361 0.63981 5.35304  70
12      17 13.6150 1.42417 6.97699  24
13      18 13.5310 1.09328 6.08715  31
30.2.2 Grouped data scatterplot
ggplot(data = CPS5grouped, mapping = aes(x = EDgroup, y = AvWage)) + geom_point(mapping = aes(size = N)) +
    geom_smooth(method = "lm") + labs(x = "Education (years)", y = "Average wage ($)")
30.2.3 Grouped regression summary
The group means lie close to a line, and their unweighted regression has an \(R^2\) above 0.9. This describes variation among 13 group means. The individual-level \(R^2\) also includes variation among people within each education group, so the two values are not directly comparable.
Call:
lm(formula = AvWage ~ EDgroup, data = CPS5grouped)

Residuals:
    Min      1Q  Median      3Q     Max
-1.5637 -0.7350  0.1266  0.7158  1.3198

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept) -0.01445    0.87462  -0.017    0.987
EDgroup      0.72410    0.06958  10.406 4.96e-07 ***
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 0.9387 on 11 degrees of freedom
Multiple R-squared:  0.9078,    Adjusted R-squared:  0.8994
F-statistic: 108.3 on 1 and 11 DF,  p-value: 4.958e-07
30.2.4 The problem with equal weighting
The first point represents only three people, yet the unweighted fit gives it the same influence as the much larger 12-, 14- and 16-year education groups. If we want each employee to contribute equally, we need to weight those group means by their sizes.
The individual data show more variation because they retain the differences between people within each education group. The grouped and ungrouped fits therefore describe different response variation; we should not read their \(R^2\) values as a direct comparison of predictive quality.
30.3 Ungrouped CPS5 data
What does the relationship look like when we use individual values in place of group means?
  ED SO BL HP FE MS EX UN   WG
1 10  0  0  0  0  1 27  0  9.0
2 12  0  0  0  0  1 20  0  5.5
3 12  0  0  0  1  0  4  0  3.8
4 12  0  0  0  1  1 29  0 10.5
5 12  0  0  0  0  1 40  1 15.0
6 16  0  0  0  1  1 27  0  9.0
30.3.1 Ungrouped scatterplot
ggplot(data = CPS5, mapping = aes(x = ED, y = WG)) + geom_point() + geom_smooth(method = "lm") +
    labs(x = "Education (years)", y = "Wage ($)")
`geom_smooth()` using formula = 'y ~ x'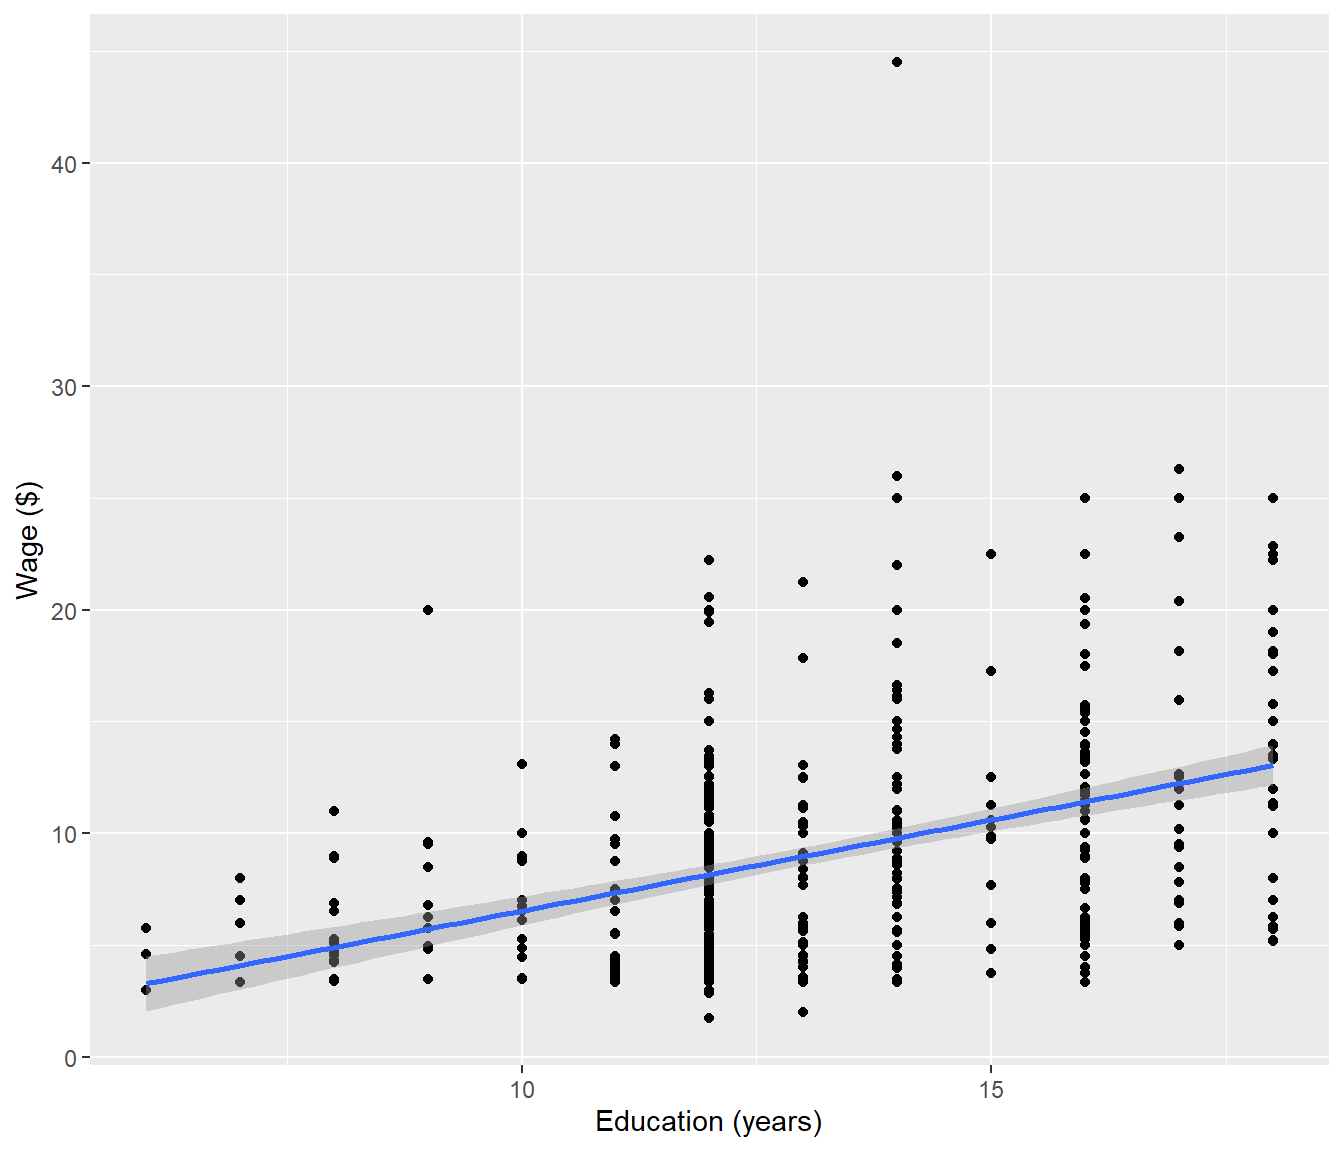
30.3.2 Ungrouped regression summary
Call:
lm(formula = WG ~ ED, data = CPS5)

Residuals:
   Min     1Q Median     3Q    Max
-8.068 -3.163 -0.700  2.289 34.709

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept) -1.60468    1.10318  -1.455    0.146
ED           0.81395    0.08281   9.829   <2e-16 ***
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 4.733 on 526 degrees of freedom
Multiple R-squared:  0.1552,    Adjusted R-squared:  0.1536
F-statistic:  96.6 on 1 and 526 DF,  p-value: < 2.2e-16
We see there is an outlier, which could be a typo (decimal point in the wrong place?) However the main focus here is that there is a lot more variation among the individual data than there is among the averaged data, so the \(R^2\) is much lower. Also the regression coefficients have different values.
30.4 Why Grouped Regression Results Differ
Formulas not examinable but conclusion is important.
To explain the difference between these two regressions, consider the regression of \(Y\) on \(X\) for all individuals, and the regression of group means \(\bar Y\) on \(\bar X\). In the CPS5 example, everyone within an education group has the same ED value, so \(x_{ij}=\bar x_j\). The equivalence below depends on that condition.
In Least Squares we choose \(\beta_0\) and \(\beta_1\) to minimise
\[SS_{error} = \sum^n_{i=1}(y_i - \beta_0- \beta_1 x_i)^2 ~~~~ (1) \]
However the regression for the averages treats all \(m\) groups as being of equal worth:
\[ \sum^m_{j=1}(\bar y_j - \beta_0- \beta_1 \bar x_j)^2 ~~~~~~ (2) \]
That is, the computations will try just as hard to fit a value that arises from a small group of data as a value from a large group.
30.5 Error SS decomposition
But in fact we don’t have all the \(y_{ij}\) equal. Instead what we do is to add and subtract \(\bar y_j\) inside the parentheses in equation (3), and then expand the square: \[\begin{aligned}SS_{error} &= \sum^m_{j=1}\sum^{n_j}_{i=1}(y_{ij} -\bar y_j + \bar y_j - \beta_0- \beta_1 x_{ij})^2\\&= \sum^m_{j=1}\sum^{n_j}_{i=1}(y_{ij} -\bar y_j)^2 + \sum^m_{j=1}\sum^{n_j}_{i=1}(\bar y_j - \beta_0- \beta_1 \bar x_j)^2 ~~~~~(*)\\&= \sum^m_{j=1}\sum^{n_j}_{i=1}(y_{ij} -\bar y_j)^2 + \sum^m_{j=1} n_j~(\bar y_j - \beta_0- \beta_1 \bar x_j)^2\end{aligned}\]
(*) Equality happens because the cross-product term \(\sum^m_{j=1} \sum^{n_j}_{i=1} ~2~(y_{ij} -\bar y_j) (\bar y_j - \beta_0- \beta_1 \bar x_j) =0\).
30.5.0.1 Key insight: SS decomposition
The key fact is that the error SS splits into two parts:
\[SS_{error} = \sum^m_{j=1}\sum^{n_j}_{i=1}(y_{ij} -\bar y_j)^2 + \sum^m_{j=1} n_j~(\bar y_j - \beta_0- \beta_1 \bar x_j)^2\] - The first term is the “pure error” sum of squares. It records how much individual wages vary around their education-group means \(\bar y_j\). - The second term is the weighted sum of squares for fitting the group means, with each squared residual multiplied by the group size \(n_j\).
Because everyone in an education group has the same ED value, the within-group sum of squares does not depend on the regression coefficients. Minimising the individual-level sum of squares therefore gives the same intercept and slope as a regression of the group means weighted by group size. This equality of coefficient estimates depends on the predictor being constant within each group. It does not say that the two analyses have the same residual degrees of freedom, standard errors or R-squared: the grouped analysis has lost the within-group variation.
30.6 Weighted regression in R
To do a weighted regression we have to specify weights in the lm() command. Below we compare the weighted least squares (WLS) estimates from the averaged data to the ungrouped ordinary least squares (OLS) estimates from the raw data.
Call:
lm(formula = AvWage ~ EDgroup, data = CPS5grouped, weights = N)

Weighted Residuals:
   Min     1Q Median     3Q    Max
-6.944 -3.971  2.699  4.151  9.217

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept) -1.60468    1.27442  -1.259    0.234
EDgroup      0.81395    0.09567   8.508 3.62e-06 ***
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 5.467 on 11 degrees of freedom
Multiple R-squared:  0.8681,    Adjusted R-squared:  0.8561
F-statistic: 72.39 on 1 and 11 DF,  p-value: 3.621e-06
30.6.0.1 OLS comparison
Call:
lm(formula = WG ~ ED, data = CPS5)

Residuals:
   Min     1Q Median     3Q    Max
-8.068 -3.163 -0.700  2.289 34.709

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept) -1.60468    1.10318  -1.455    0.146
ED           0.81395    0.08281   9.829   <2e-16 ***
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 4.733 on 526 degrees of freedom
Multiple R-squared:  0.1552,    Adjusted R-squared:  0.1536
F-statistic:  96.6 on 1 and 526 DF,  p-value: < 2.2e-16
The weighted group-mean fit gives the same intercept and slope as the individual-level fit, apart from rounding in the supplied means. Education is constant within each group. The standard errors and \(R^2\) need not match: the grouped fit has only 13 rows and does not include the within-group variation in wages.
30.7 Comparing WLS vs OLS plots
The following plot shows the averaged data with the unweighted (dashed) and weighted (solid red) lines. The weighted line is closer to where more data are.
ggplot(data = CPS5grouped, mapping = aes(x = EDgroup, y = AvWage)) + geom_point(mapping = aes(size = N)) +
    geom_smooth(method = "lm", mapping = aes(weight = N), col = "red", se = FALSE) +
    geom_smooth(method = "lm", linetype = "dashed", se = FALSE) + labs(x = "Education (years)",
    y = "Average wage ($)")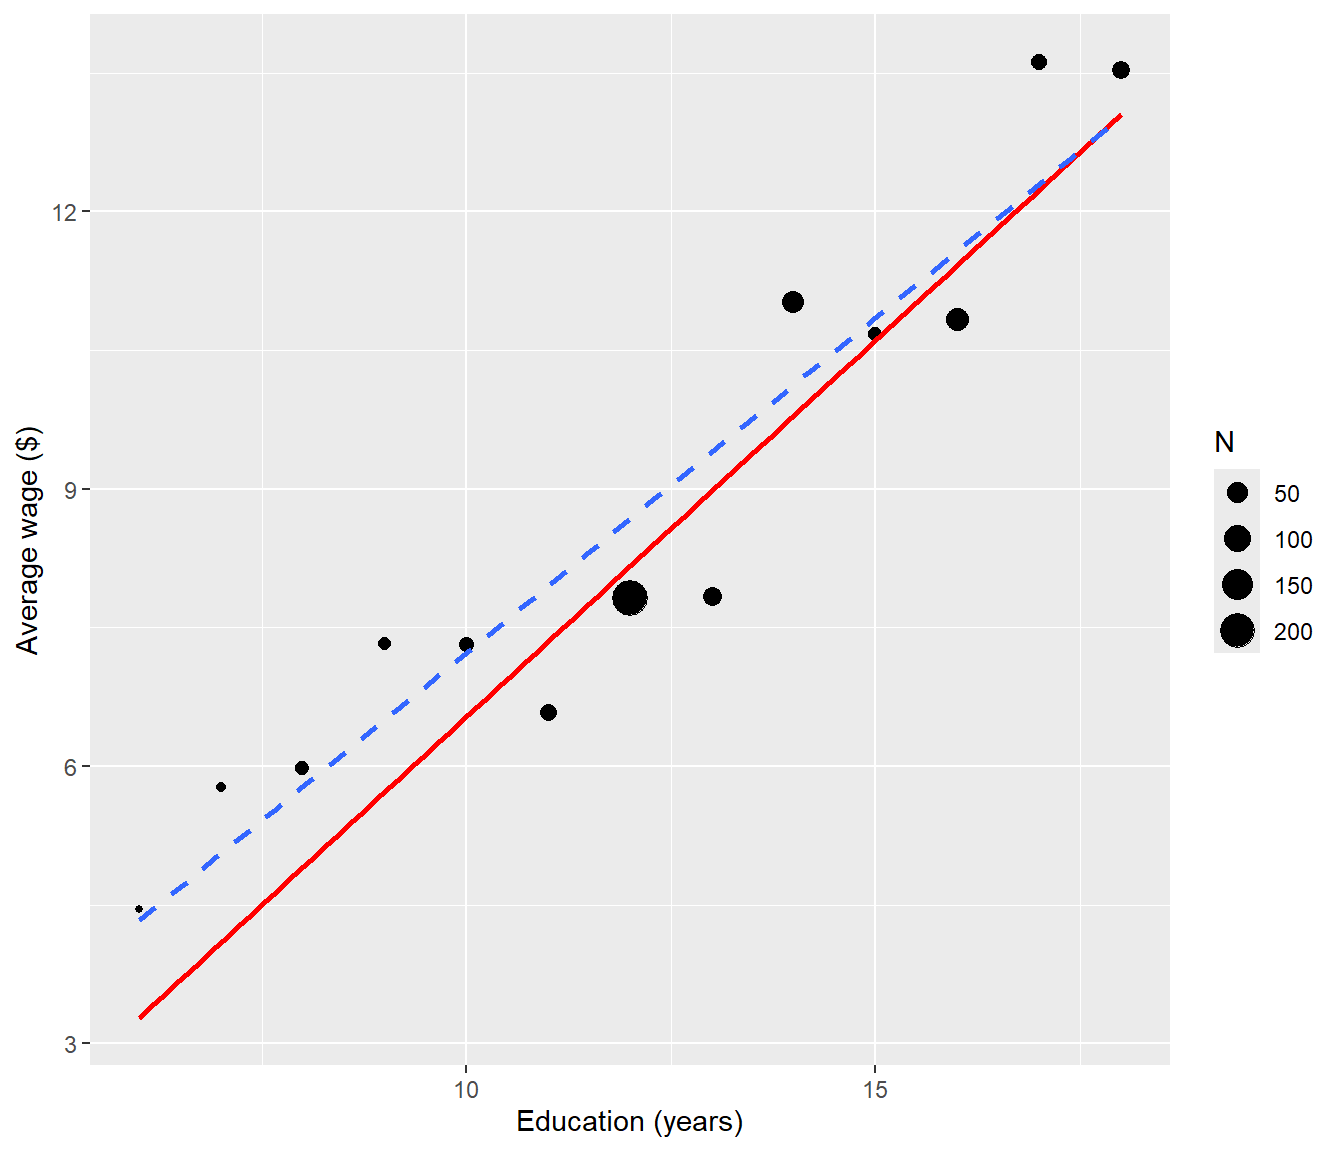
30.8 Residuals for Weighted Regression
Clearly a plot of ordinary residuals could be misleading in the context of weighted least squares. The low weight points on the left are badly fitted and this could make them look like influential outliers.
augment(cps.wls, CPS5grouped) |>
    ggplot(mapping = aes(x = EDgroup, y = .resid)) + geom_point() + geom_hline(yintercept = 0,
    linetype = "dotted") + labs(y = "Simple residuals", x = "Education group (years)")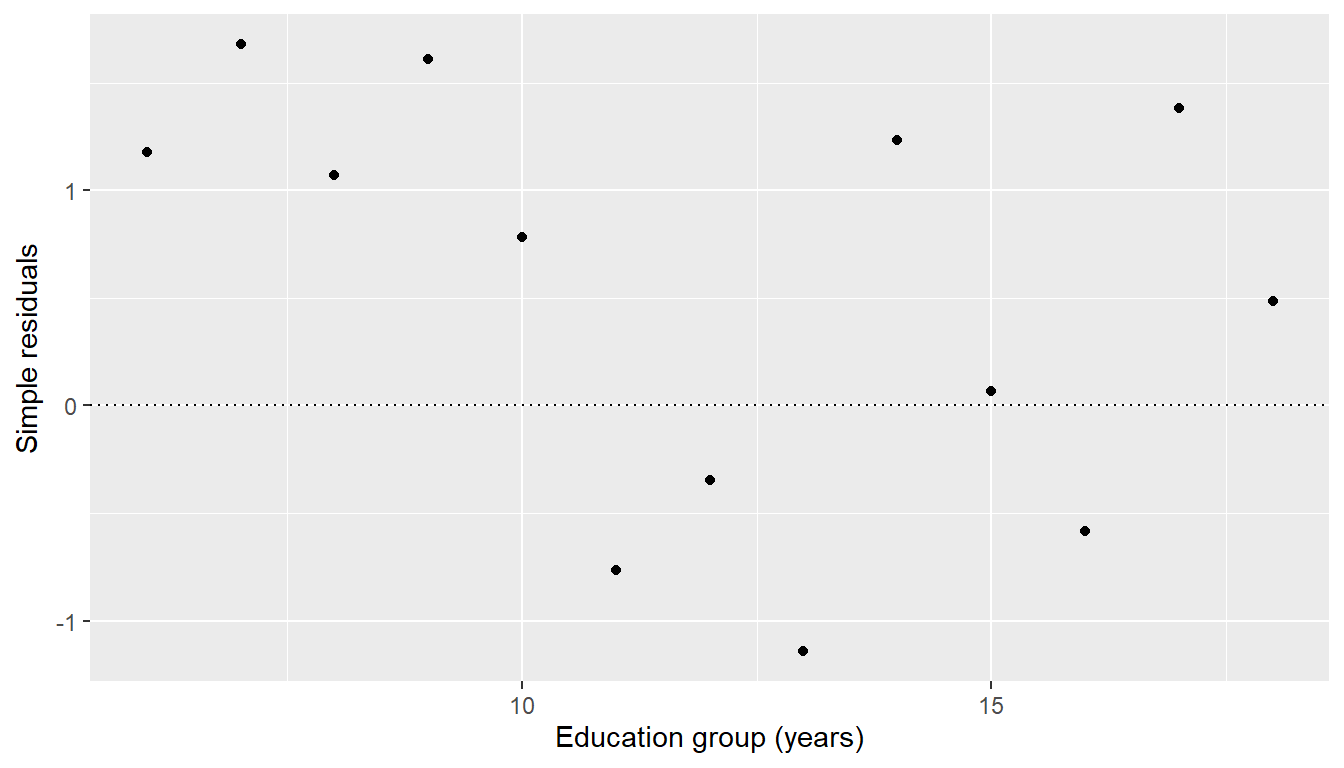
30.8.1 Pearson residuals
Instead we use weighted, or Pearson, residuals \(r_j = \sqrt{w_j}(y_j - \hat y_j)\).
augment(cps.wls, CPS5grouped) |>
    mutate(pearson = .resid * sqrt(N)) |>
    ggplot(mapping = aes(x = EDgroup, y = pearson)) + geom_point() + geom_hline(yintercept = 0,
    linetype = "dotted") + labs(y = "Pearson (weighted) residuals", x = "Education group (years)")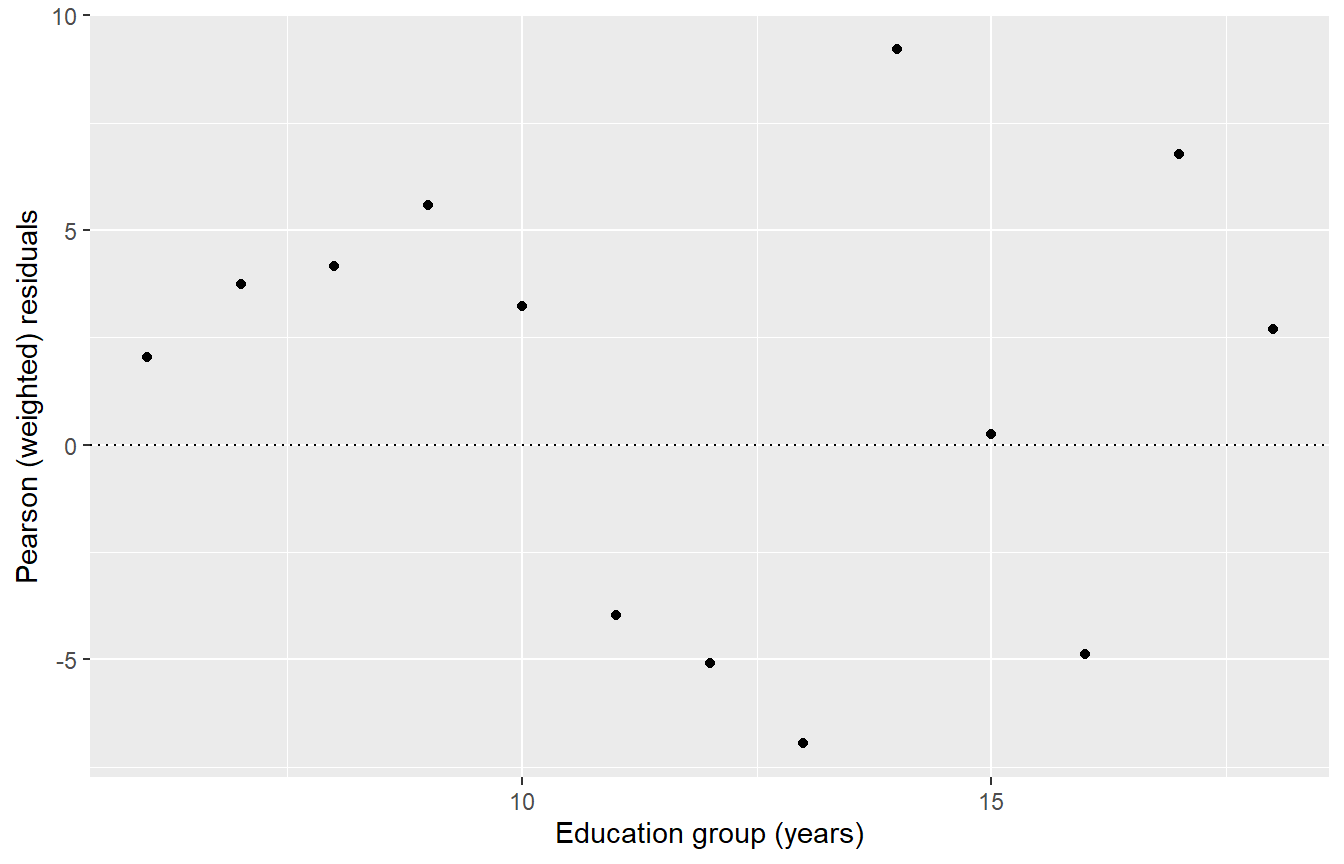
The weighted residuals are measured on the scale used by the weighted fit. A small weighted residual means the observation is close to its fitted value relative to the assumed variance; it is not a complete influence analysis and does not make a point scientifically unimportant. The ordinary and weighted residual panels have different scales, so compare their patterns rather than their vertical magnitudes.
30.9 Application: Weighting For Non-Constant Variance
Suppose we have data for which the variance is non-constant. So we want to give more weight to those points which have small variance (or are known more precisely) and give less weight to those points that have bigger variance (or are known less precisely).
This still fits with the idea that Weight represents the amount of information carried by each datapoint.
30.9.1 Supervisors and Workers
The following data is on the number of supervisors \(Y\) (e.g. team leaders) and the number of workers \(X\) at a number of industrial establishments.
The data are from the book by Chatterjee and Price “Regression Analysis by Example”
ggplot(supervisors, mapping = aes(x = X, y = Y)) + geom_point() + geom_smooth(method = "lm") +
    labs(x = "Number of workers (X)", y = "Number of supervisors (Y)")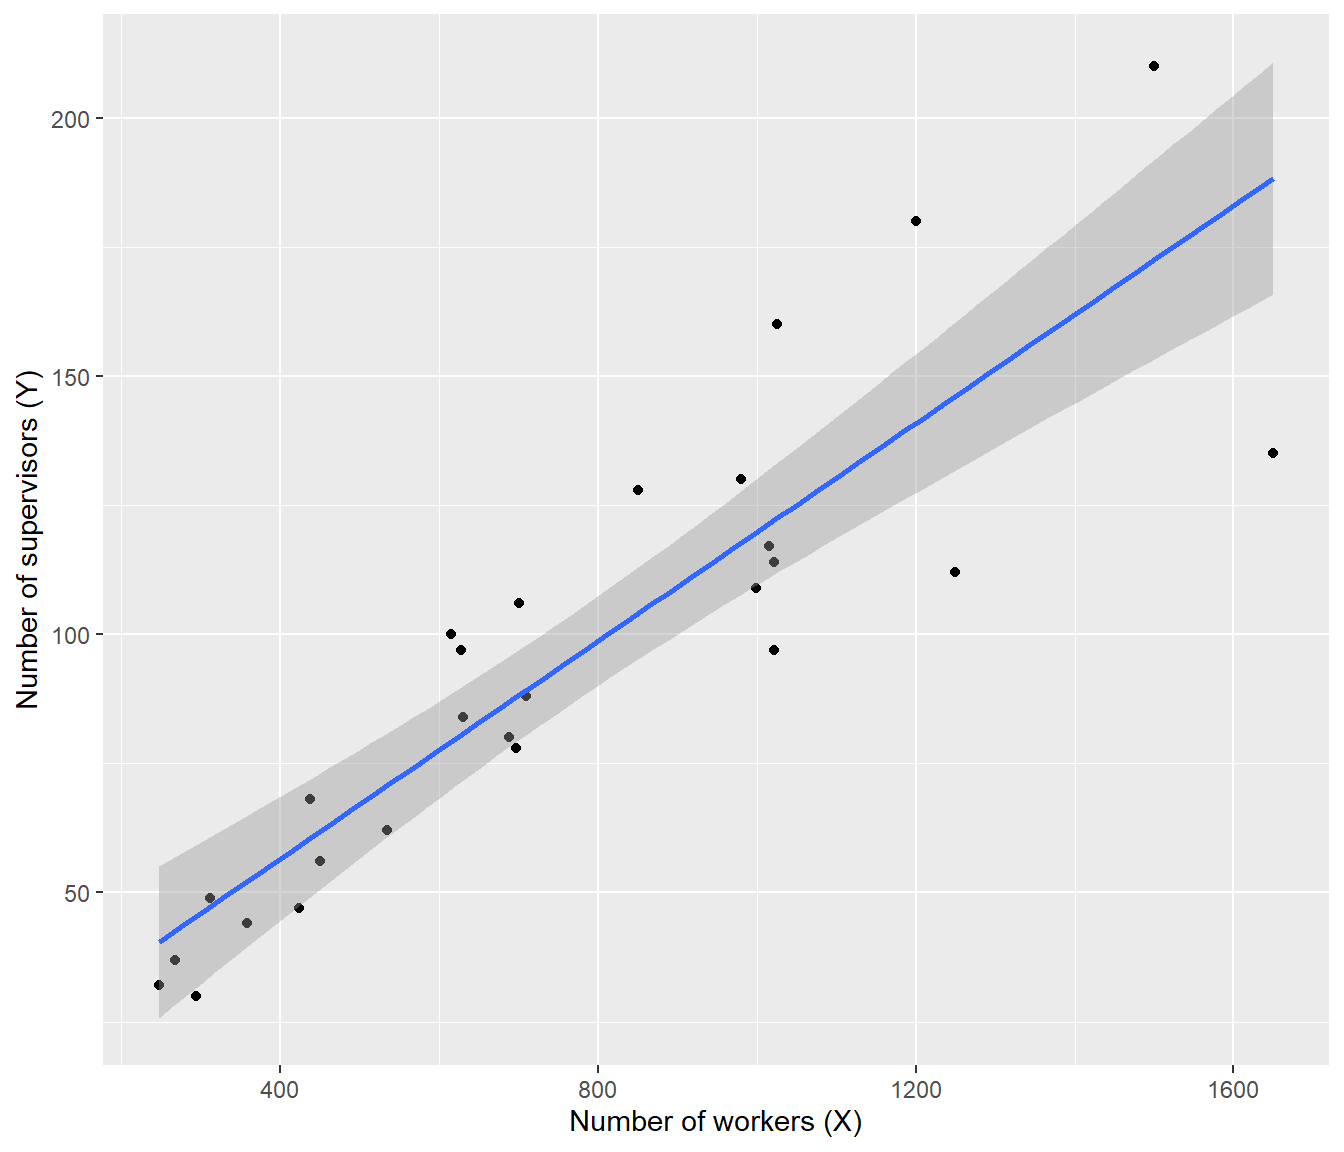
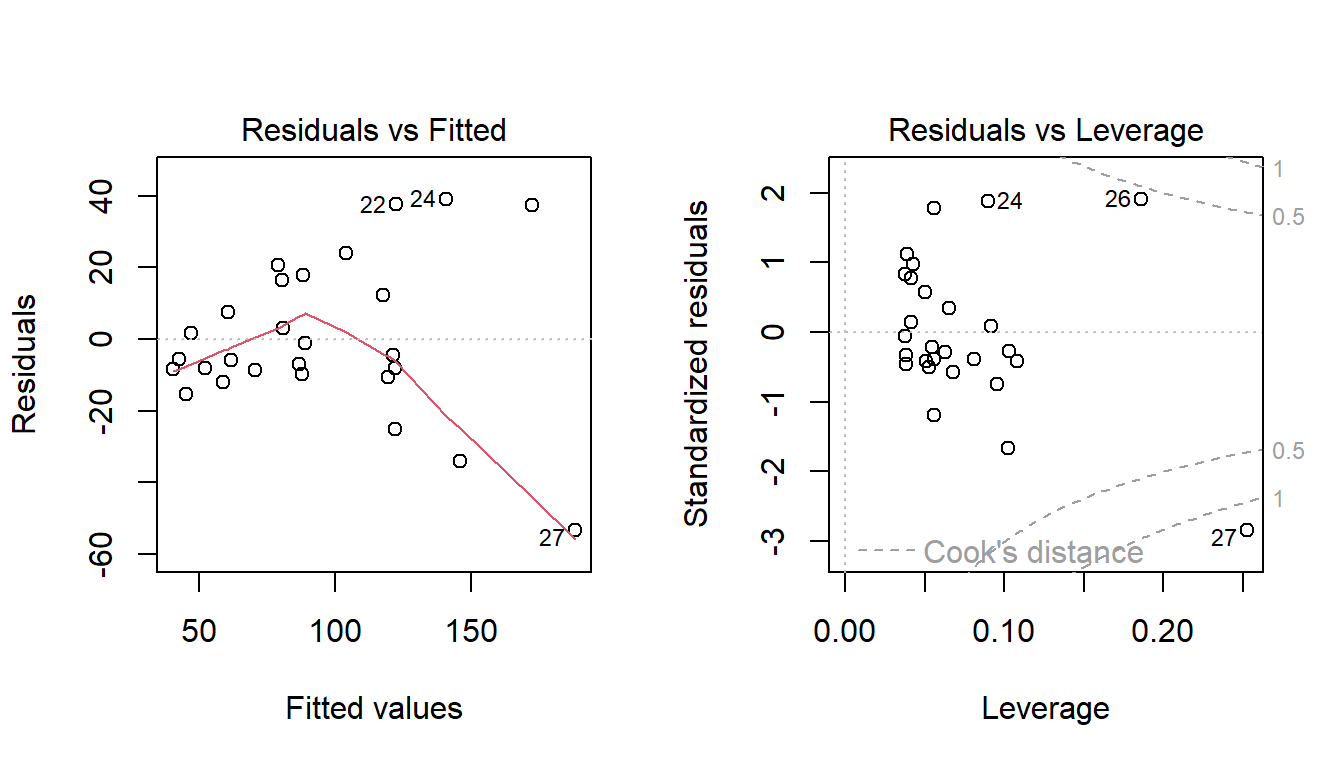
30.10 Heteroscedasticity pattern
In the residuals-versus-fitted plot, the horizontal axis shows fitted numbers of supervisors. Compare the vertical spread around fitted \(Y\) values of 50, 100 and 150. The spread increases as the fitted value rises. Since fitted \(Y\) also rises with \(X\), a reasonable working model is \(\mbox{sd}(\varepsilon_i) \propto x_i\), or \(\sigma_i=kx_i\) for some constant \(k\).
Now let us suppose we want to fit a straight-line model \[y_i = \beta_0 + \beta_1 x_i + \varepsilon_i ~ \] We would ordinarily solve this by minimising the \[SS_{error} = \sum( y_i - \beta_0 - \beta_1 x_i)^2\] where the components of the sum (the residuals \(y_i - \beta_0 - \beta_1 x_i\)) have constant standard deviation. Except now the standard deviation is not constant.
But what we could do is divide through by \(x_i\). The model becomes \[\begin{aligned}\frac{y_i}{x_i} &= \frac{\beta_0}{x_i} + \beta_1\frac{x_i}{x_i} + \frac{\varepsilon_i}{x_i}\\Y_i &=\beta_0 X_i + \beta_1 + \eta_i\end{aligned}\] where \(Y_i = \frac{y_i}{x_i}\), \(X_i = \frac{1}{x_i}\) and \(\eta_i = \frac{\varepsilon_i}{x_i}\).
30.10.1 Constant variance after transformation
The error term \(\eta_i\) now has constant standard deviation as
\[\mbox{sd}\left( \frac{\varepsilon_i}{x_i}\right) = \frac{ kx_i}{x_i} = k.\]
We now have a linear model with constant variance so can solve by least squares in the usual way.
We could do the transformation ourselves and then just use lm() normally, but another way to look at it is we’re minimising
\[\sum \left(\frac{y_i}{x_i} - \frac{\beta_0}{x_i} - \beta_1 \right)^2 ~~= ~~ \sum \frac{1}{x_i^2}\left(y_i - \beta_0 -\beta_1 x_i \right)^2\]
which is a weighted regression with \(w_i = 1/ x_i^2\). So the task with this transformation is the same as weighted least squares with these weights.
30.11 WLS for supervisors
Call:
lm(formula = Y ~ X, data = supervisors, weights = 1/X^2)

Weighted Residuals:
      Min        1Q    Median        3Q       Max
-0.041477 -0.013852 -0.004998  0.024671  0.035427

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept) 3.803296   4.569745   0.832    0.413
X           0.120990   0.008999  13.445 6.04e-13 ***
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 0.02266 on 25 degrees of freedom
Multiple R-squared:  0.8785,    Adjusted R-squared:  0.8737
F-statistic: 180.8 on 1 and 25 DF,  p-value: 6.044e-13
30.11.1 WLS vs OLS supervisors plot
ggplot(data = supervisors, mapping = aes(x = X, y = Y)) + geom_point() + geom_smooth(method = "lm",
    mapping = aes(weight = 1/X^2), col = "red", se = FALSE) + geom_smooth(method = "lm",
    linetype = "dotted", se = FALSE) + labs(x = "Number of workers (X)", y = "Number of supervisors (Y)")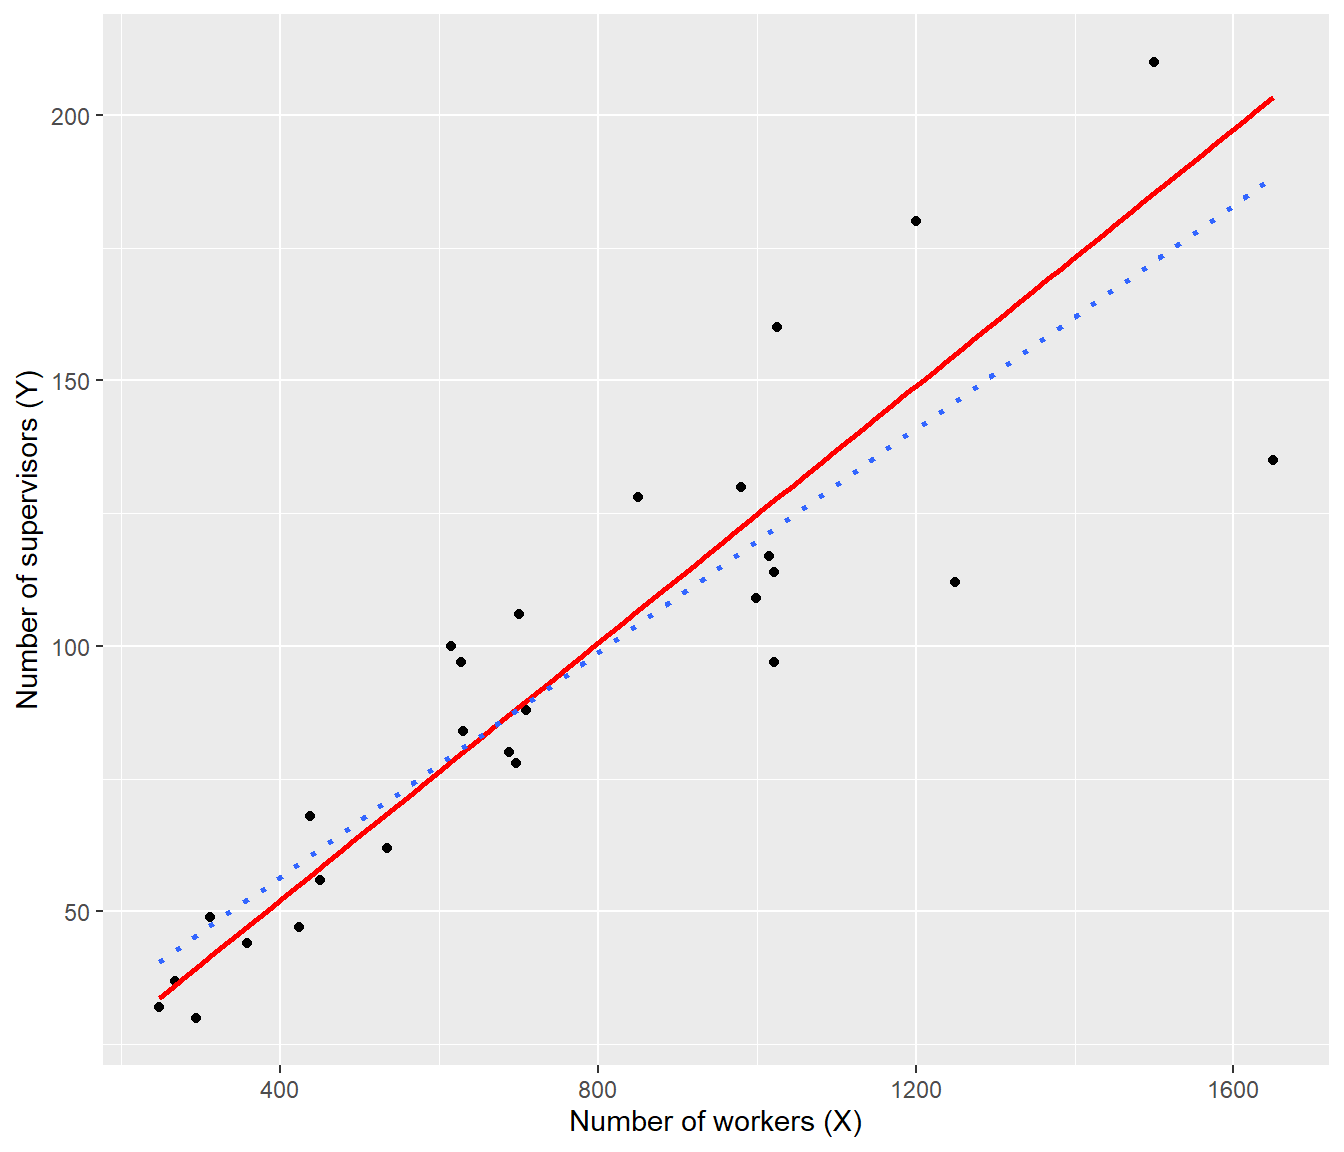
30.11.2 Weighted residuals plot
The weighted line sits closer to the low-\(X\) observations, where the assumed error variance is smaller and the weights are larger. The OLS line gives these points the same per-observation weight as the higher-\(X\) observations, despite their greater residual spread.
Let’s check the weighted residuals below. Their spread is more similar across the range of \(X\), although a little curvature may remain. This is more consistent with the proposed variance model; the plot cannot establish that the variance is exactly constant.
augment(sup.wls) |>
    mutate(pearson = .resid/X) |>
    ggplot(mapping = aes(x = X, y = pearson)) + geom_point() + geom_hline(yintercept = 0,
    linetype = "dotted") + labs(y = "Pearson (weighted) residuals", x = "Number of workers (X)")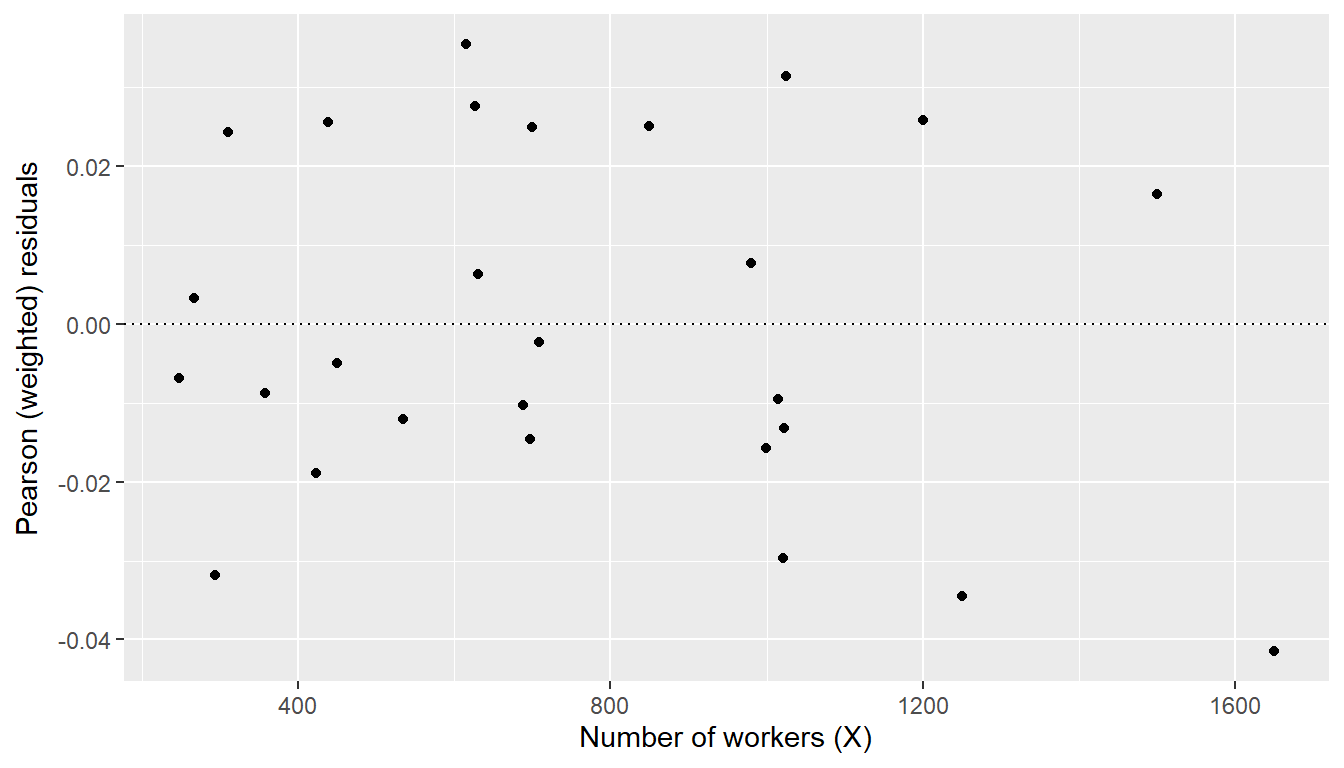
30.12 Application: Meta Analysis CPS5grouped data
Meta-analysis combines estimates from several studies. In a simple inverse-variance meta-analysis, each study contributes an estimate with its own standard error. The estimate is what we weight, so its weight is proportional to \(1/\mathrm{SE}^2\). An estimate with a smaller standard error contributes more.
In the CPS5 grouped data, each row is a mean wage for N employees. The StDev column estimates the standard deviation of individual wages within that group. The variance of the group mean is therefore approximately \(\mathrm{StDev}_j^2/n_j\), giving the weight \(w_j=n_j/\mathrm{StDev}_j^2\). This uses both group size and the variation among employees in each group.
CPS5weighted <- CPS5grouped |> mutate(Wt = N/ StDev^2)
cps.wls2 <- lm(AvWage ~ EDgroup, weights=Wt, data=CPS5weighted)
summary(cps.wls2)
Call:
lm(formula = AvWage ~ EDgroup, data = CPS5weighted, weights = Wt)

Weighted Residuals:
    Min      1Q  Median      3Q     Max
-1.4367  0.1153  0.7399  1.0895  1.7058

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept)  0.26605    0.93427   0.285    0.781
EDgroup      0.65602    0.07828   8.381 4.19e-06 ***
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 1.21 on 11 degrees of freedom
Multiple R-squared:  0.8646,    Adjusted R-squared:  0.8523
F-statistic: 70.24 on 1 and 11 DF,  p-value: 4.186e-06
30.12.1 CPS5 re-weighted plot
ggplot(data = CPS5weighted, mapping = aes(x = EDgroup, y = AvWage)) + geom_point(mapping = aes(size = N)) +
    geom_smooth(method = "lm", mapping = aes(weight = Wt), col = "red", se = FALSE) +
    geom_smooth(method = "lm", mapping = aes(weight = N), linetype = "dotted", se = FALSE) +
    labs(x = "Education group (years)", y = "Average Wage ($)")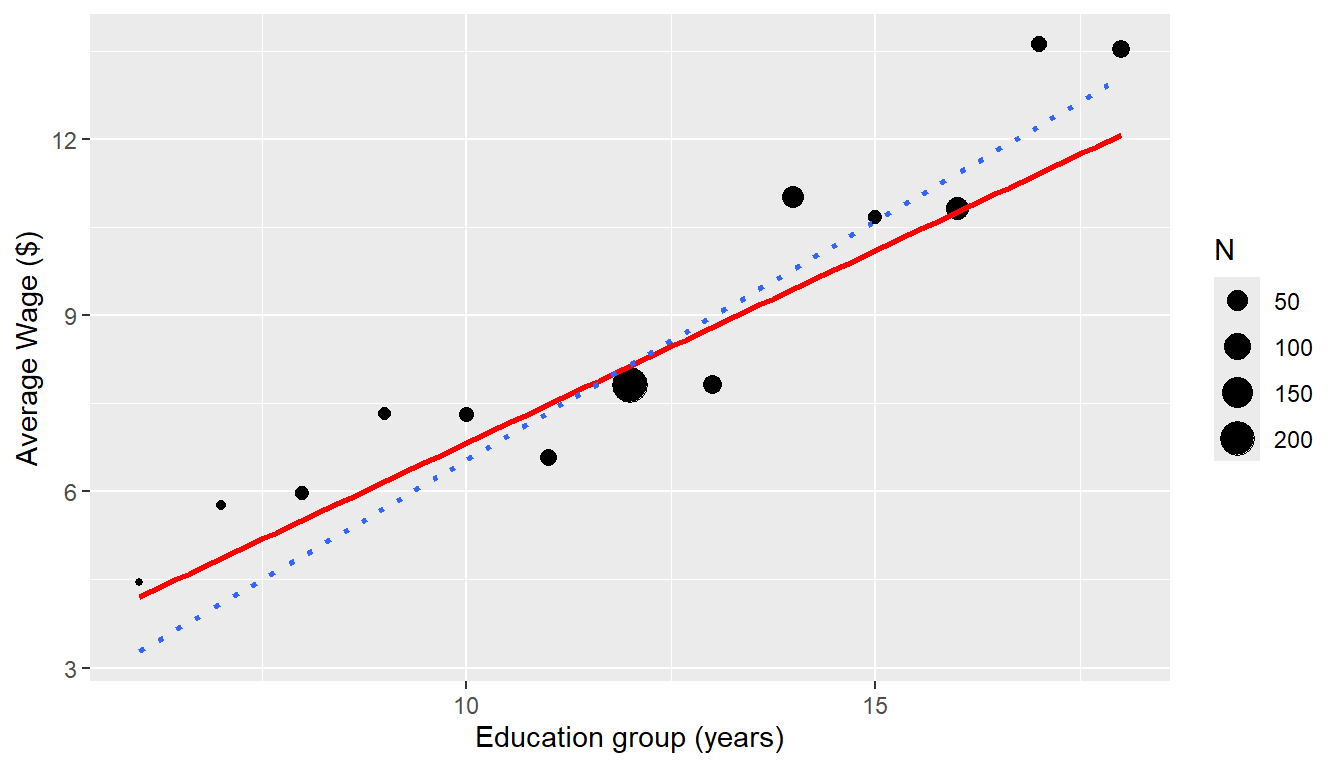
The standard deviations are much higher for the highly-educated groups, so that counteracts some of the effect of higher sample sizes.
30.13 Running Example: Weighted Summaries for Seoul Bike Data
The Seoul bike data also show why grouped summaries need care. If we average demand within temperature bands, some groups represent many more hourly observations than others.
seoul_grouped = seoul_hourly |>
    mutate(temp_band = cut(temperature, breaks = c(-20, -10, 0, 10, 20, 30, 40),
        include.lowest = TRUE)) |>
    group_by(temp_band) |>
    summarise(avg_bike_count = mean(rented_bike_count), avg_temperature = mean(temperature),
        N = n(), .groups = "drop")

seoul_grouped
# A tibble: 6 × 4
temp_band avg_bike_count avg_temperature N
<fct> <dbl> <dbl> <int>
1 [-20,-10] 141. -12.7 228
2 (-10,0] 210. -4.19 1226
3 (0,10] 425. 5.04 2143
4 (10,20] 765. 15.3 2264
5 (20,30] 1120. 24.5 2387
6 (30,40] 1106. 33.0 512ggplot(seoul_grouped, aes(x = avg_temperature, y = avg_bike_count)) + geom_point(aes(size = N)) +
geom_smooth(method = "lm", se = FALSE, linetype = "dashed") + geom_smooth(method = "lm",
aes(weight = N), se = FALSE, colour = "red") + labs(x = "Average temperature within band",
y = "Average bike demand", title = "Aggregated groups with different support should not be treated equally")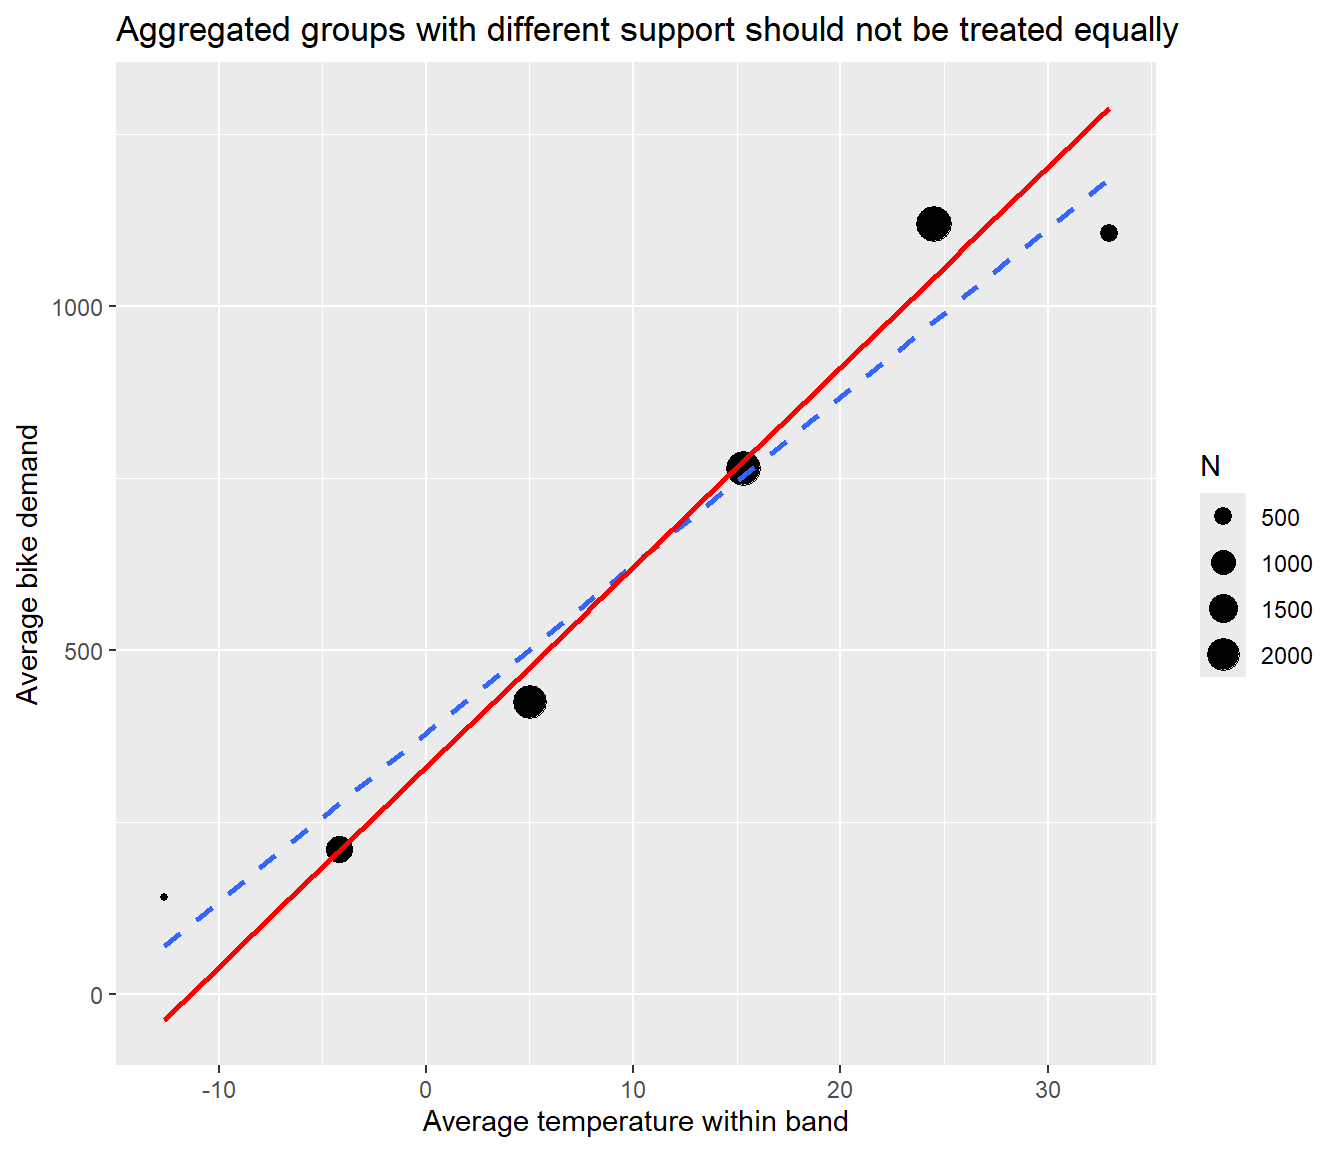
These temperature bands summarise unequal numbers of hours. Weighting a band’s mean by its count changes how much that summary influences the line. Here temperature also varies within each band, so the line through weighted band means need not be identical to a line fitted to all the hourly observations. The exact equality in the education example relied on everybody in a group having the same predictor value.
30.14 Putting the weights together
We have now used four forms of weight. In every case, start with the variance of the response represented by one row, then take its reciprocal.
| What one row represents | Variance of that row | Relative weight | Example in this lecture |
|---|---|---|---|
| A mean of \(n_j\) independent people, with a common individual variance \(\sigma^2\) | \(\sigma^2/n_j\) | \(n_j\) | First CPS5 grouped fit, weights=N |
| An observation or estimate with variance \(v_i\) | \(v_i\) | \(1/v_i\) | General rule; study estimates in meta-analysis |
| A mean of \(n_j\) independent people, with individual variance \(\sigma_j^2\) in group \(j\) | \(\sigma_j^2/n_j\) | \(n_j/\sigma_j^2\) | CPS5 re-weighted fit, weights=N/StDev^2 |
| An observation whose error standard deviation is proportional to \(x_i\) | \(k^2x_i^2\) | \(1/x_i^2\) | Supervisors and workers, weights=1/X^2 |
The extra \(n_j\) in \(n_j/\sigma_j^2\) comes from averaging: the variance of a mean of \(n_j\) independent observations is the individual variance divided by \(n_j\). Likewise, \(1/x_i^2\) follows from inverse variance when the error standard deviation is \(kx_i\). A constant shared by every row, such as \(\sigma^2\) or \(k^2\), can be left out of the relative weights.